
THE PRACTICAL ANSWER
The selected 1017 results describe two complete serving configurations, not an isolated engine-only test. Keep the converted weights and separate Engram revision, distinguish October 17 decode from October 18 prefill, and retain missing image, cache and quality evidence.
There is now a community report that explicitly names DeepSeek-V4.1-Flash-1017 on a pair of DGX Sparks. Its useful contribution is a traceable model view, saved results and documented failure boundaries. Treat it as evidence for those particular configurations. It does not establish an engine-wide speed advantage or general model quality.
This note reads Elevatormusic’s pinned recipe, including the October 17 comparison and the separate October 18 follow-up. Run AI Here has not run this model or reproduced the author’s results.
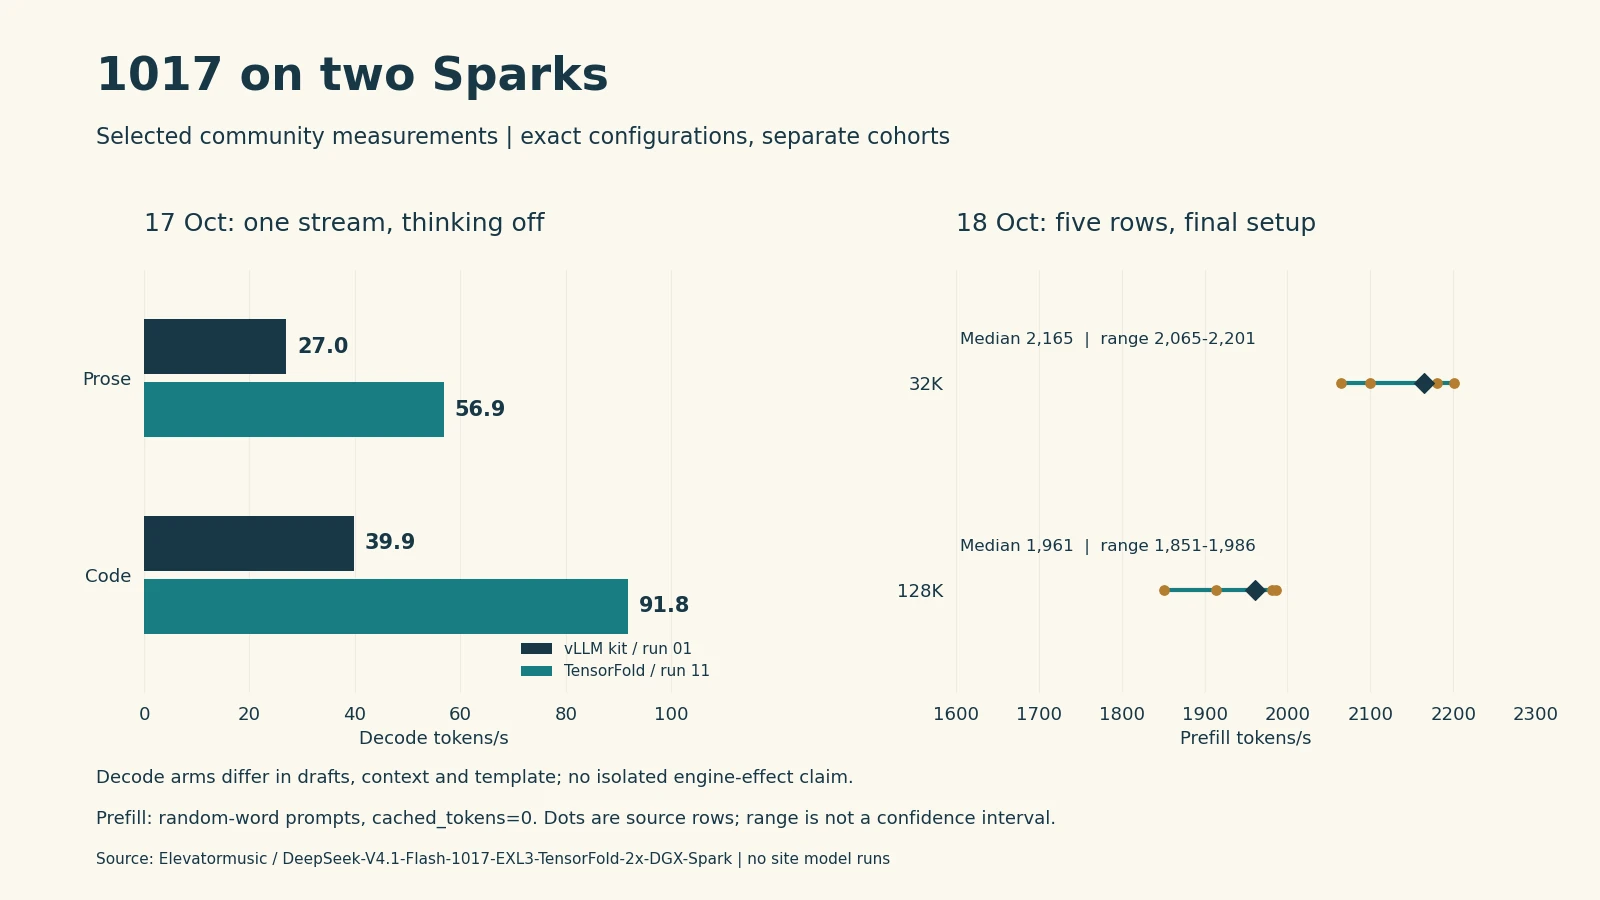
Figure: drawn directly from selected source values. The two decode arms and the later prefill cohort are separate. Prefill whiskers show an observed minimum and maximum, not a confidence interval.
First verify which 1017 files were served
The author combines LibertAIDAI/DeepSeek-V4.1-Flash-1017-EXL3-2.9bpw at afc7aa0aab98ee735c0f54e0a122019af1ac08f1 with two Engram shards from deepseek-ai/DeepSeek-V4.1-Flash-1017 at 1bae0e1088993b9b82de08f59de5be5a34e42170. This identifies an EXL3 conversion and its separate base-model tables. It is not a measurement of the unconverted official checkpoint. Model-view provenance.
The pinned limits document says that the measured conversion revision was already behind a newer card revision. The author did not compare them. Keep the measured revision when reusing a number; a current download is not automatically the same artifact.
Keep one named build beside each decode value
These selected observations use one request, thinking off and two prompts per workload. The suite streams with max_tokens=700, temperature 1.0 and top-p 1.0. Actual output lengths and exact prompt-token counts are not supplied in the selected result rows. Decode excludes the first-token wait: (completion_tokens − 1) / (stream end − first content-bearing chunk).
| October 17 arm | Prose decode, tokens/s | Code decode, tokens/s |
|---|---|---|
| vLLM kit, run 01 | 27.0 | 39.9 |
| TensorFold, run 11 | 56.9 | 91.8 |
Each cell is the source’s rounded mean of two prompt-level rates within one run. It has no supplied repeated-run uncertainty. Original vLLM result, original TensorFold result.
The report’s headline median combines six different TensorFold builds. It is not six repetitions of this run-11 configuration. The selected values above deliberately identify one build instead of hiding that distinction.
The comparison changes more than the engine
Both arms use the same reported model view and Spark pair, but their serving settings differ. The vLLM kit uses an exllamav3 overlay, three draft tokens, one configured sequence, a 262,144-token cap and 1,536-token batching. TensorFold run 11 uses Python 0.6.6 at fd2365042f56fcf726cf4071132c8b779ad2eae0, five drafts, capacity for four requests, a 1,048,576-token cap and 2,048-token prefill chunks. The source also records a template patch, with its per-run use inferred from file times. Comparison conditions.
The baseline image digest is retained in JSON. The TensorFold executed image digest is unknown. The recipe now builds a later 92aa710b533d revision prefix. Do not attach the October 17 decode cells to that later build or describe this as an isolated engine-only experiment. No multi-user vLLM comparison was measured.
The newer long-prompt cohort answers a different question
The October 18 final setup uses random-word prompts and records zero cached tokens. Five source rows give:
| Prompt bucket | Median prefill, tokens/s | Observed range |
|---|---|---|
| 32K | 2,165 | 2,065–2,201 |
| 128K | 1,961 | 1,851–1,986 |
The denominator is prompt tokens divided by TTFT. These runs include a defined warm-up sequence, Engram page handling and host memory controls. They are separate from the older suite’s repeated-sentence prompts, where prefix reuse could not be ruled out. Each original row remains in the export. Final setup and five rows.
For deployment planning, inspect per-node disk, runtime cache and memory headroom separately. The author requires a substantial local model view and additional first-start cache. Host tuning affects the whole machine: read the original settings and their measured scope before adopting them. This article does not execute or prescribe them for your cluster.
What the tests still leave open
The author reports two near-million-token needle tests, with about 1.7 GiB available on the head at the memory low point. A retrieved fact does not validate general long-context reasoning, near-limit concurrent sessions or decode speed. Image input was not tested. Neither the task suite nor the weights’ separate perplexity claim establishes this engine’s general accuracy. Some slower states remain unexplained. Known limits.
Use this recipe as a concrete reproduction candidate. Preserve the model view, exact arm, template, draft depth, cache state and request shape before judging a local result. The JSON source record and adjacent article exports keep those fields with the six selected measurements.
Continue with the source material
Original sources and evidence boundary
Checked 2026-10-18. Source declarations and community measurements retain their own conditions. No independent model benchmark was run by Run AI Here.
- Elevatormusic · README.md Document revision:
9c6ab02340b770c6c3e1a9a4d5e70a56c5829d32Document checksum and matching source record
SHA-256
Read source conditions →546a0c3bfbbb6e84226ec812cf38927f6d993e53b73633a540c426eea5f13d29 - Elevatormusic · docs/BENCHMARKS.md Document revision:
9c6ab02340b770c6c3e1a9a4d5e70a56c5829d32Document checksum and matching source record
SHA-256
Read source conditions →b2d05a077ae8145a2cf2a98ac2ae2eabef87b992230c32398a60e0a2e9174861 - Elevatormusic · docs/KNOWN-LIMITS.md Document revision:
9c6ab02340b770c6c3e1a9a4d5e70a56c5829d32Document checksum and matching source record
SHA-256
Read source conditions →eeb6bc6f7a3fce20654f977581e9718b124e70fc01ab358efebefe9afd9dc942 - Elevatormusic · runs/2026-10-17/PROVENANCE.md Document revision:
9c6ab02340b770c6c3e1a9a4d5e70a56c5829d32Document checksum and matching source record
SHA-256
Read source conditions →aa020bd6aa0fe840c9518c96dbc00f04bbdf6add834f2fe7bac2b076aa91a089 - Elevatormusic · runs/2026-10-18/INDEX.md Document revision:
9c6ab02340b770c6c3e1a9a4d5e70a56c5829d32Document checksum and matching source record
SHA-256
Read source conditions →e69d8c270e6407ddbaacb82da36cc48994b6f20fd4300d176753371b4e23fb8e - Elevatormusic · runs/2026-10-17/01_vllm-miaai-kit_suite-results_32of32.json Document revision:
9c6ab02340b770c6c3e1a9a4d5e70a56c5829d32Document checksum and matching source record
SHA-256
Read source conditions →0cb7c61b5b321ba0b9eec76460e4d9d3d0e759bd09cfb03fc747ef66e7c2ea63 - Elevatormusic · runs/2026-10-17/11_tensorfold-fd2365042f56_suite-results_32of32.json Document revision:
9c6ab02340b770c6c3e1a9a4d5e70a56c5829d32Document checksum and matching source record
SHA-256
Read source conditions →d0ec8c99b0208ac4ddc272379d3cd71c796b5662d09481d6ba1e98fbbf0fa41c - deepseek-ai · README.md Document revision:
1bae0e1088993b9b82de08f59de5be5a34e42170Document checksum and matching source record
SHA-256
Read source conditions →b72b796e4f4c739eca5d0ad360a7679b39118ca7eb64891f7151a527b292c42a
AI-assisted draft, reviewed and edited by Run AI Here. Selected source measurements. Decode uses the two named October 17 arms; prefill is the separate October 18 final setup. Dots show five original row values; ranges are observed minima/maxima, not confidence intervals. Original authors retain attribution. Corrections should identify the source revision and affected statement.