
THE PRACTICAL ANSWER
The September NVFP4 report and October EXL3 correction are different deployment lines. The EXL3 author withdrew its old task scores after finding an unloaded router bias. Current evidence is a same-quant probability check; it does not revalidate old task scores or import the NVFP4 task panel.
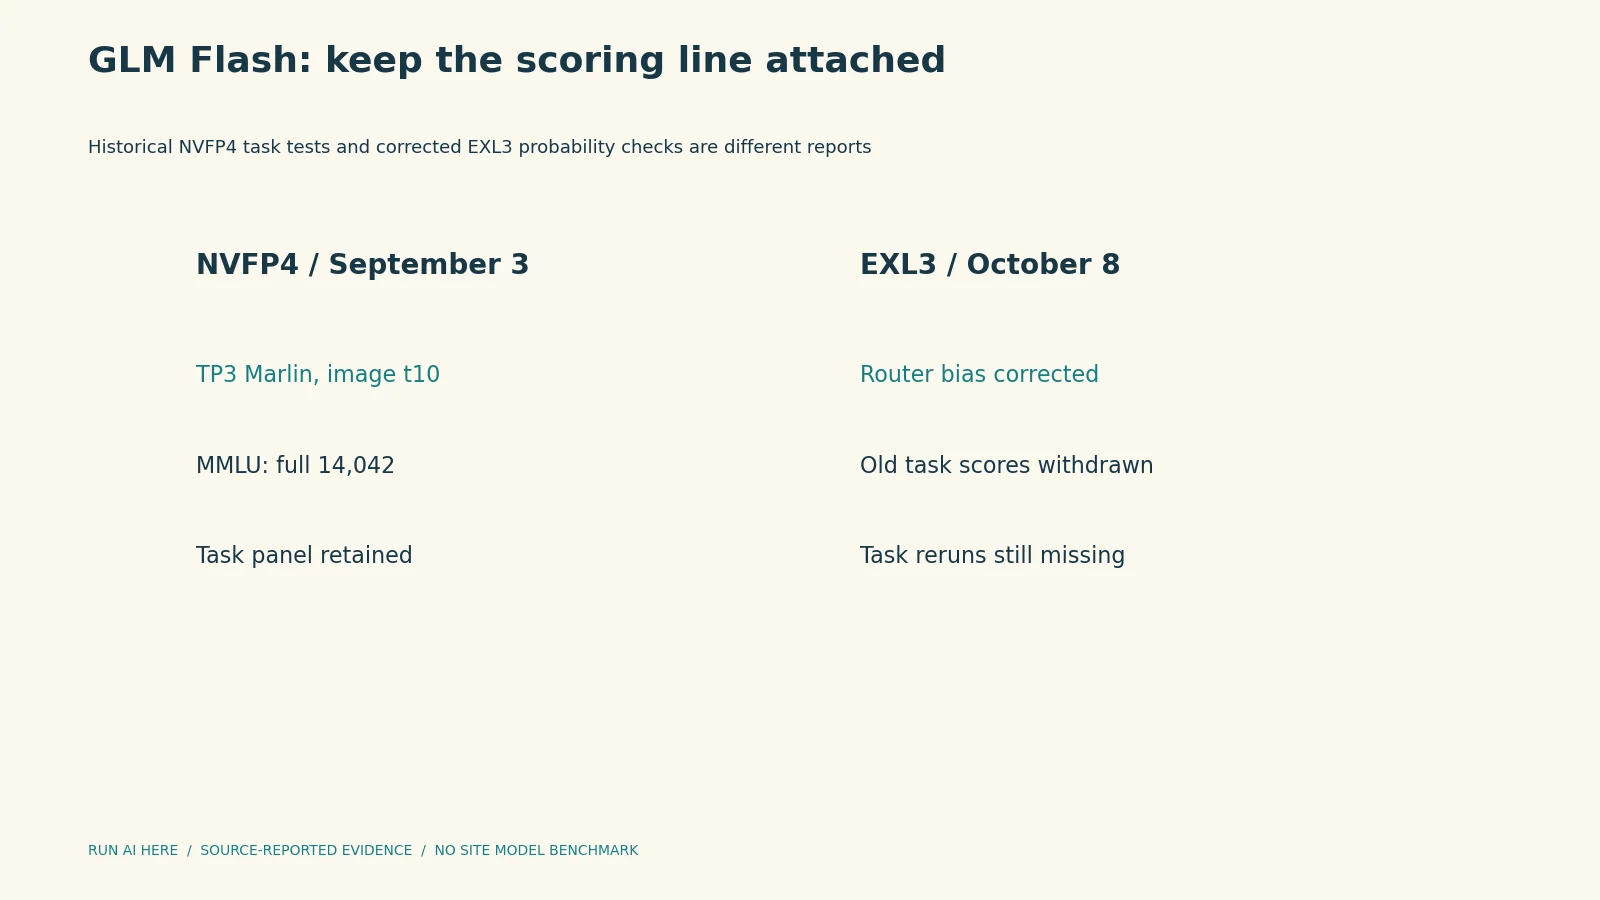
No NVFP4 score is assigned to the corrected EXL3 deployment. No cross-stack ranking.
A deployment's scores need a version history just as much as its launch command does. Two original GLM-5.3-Flash reports illustrate why: a September NVFP4 task campaign and an October EXL3 correctness investigation. Both use three DGX Sparks, but they differ in quantization, plugin, engine and measurement purpose. The EXL3 author withdrew its old task scores after finding a missing router bias. Reading both reports is useful only if their boundaries survive the summary. Run AI Here has not rerun either deployment or assigned them a combined score.
The historical NVFP4 campaign has its own identity
The September 3 benchmark ledger describes a continuous 09:08–18:08 UTC campaign using three GB10 nodes, TP3 plus expert parallelism, Marlin MoE, FP8 KV and DFlash2 k7. The image is harem/glm53-lil:t10, with a short engine identity. The configured context ceiling is 1,000,000 decimal tokens, max sequences eight and batched tokens 2,048. Memory utilization for these benchmark runs is 0.85, rather than the later production 0.88 setting.
The NVFP4 project README says this line stopped maintenance on September 6 and moved to EXL3. The old measurements remain historical observations of that stack. Their checkpoint revision and executed image digest are not pinned, so neither is manufactured from the documentation commit. Most generation tests use temperature zero with low reasoning effort; MMLU is the explicit exception because it performs loglikelihood scoring without generation or sampling.
Full MMLU is different from a small generation subset
The saved raw MMLU result gives accuracy 0.8594217347956131 and standard error 0.0028276391244761038. This is the full 14,042-question, 57-subject, zero-shot run under lm-eval 0.4.9. The uncertainty field is a harness standard error, not a repeated-trial standard deviation or a confidence interval. Replacing that meaning with a generic plus/minus label would lose useful statistical information.
The harness uses concurrency eight, a 36,000-second timeout and six retries. An initial attempt stalls around 81 percent because aiohttp's total timeout includes queued work. The repeated full run keeps the content and reports no engine errors. The failed harness attempt is not a measured zero-accuracy model run, and raising the request timeout is not an engine OOM fix. The final result and the reason for the rerun both remain queryable.
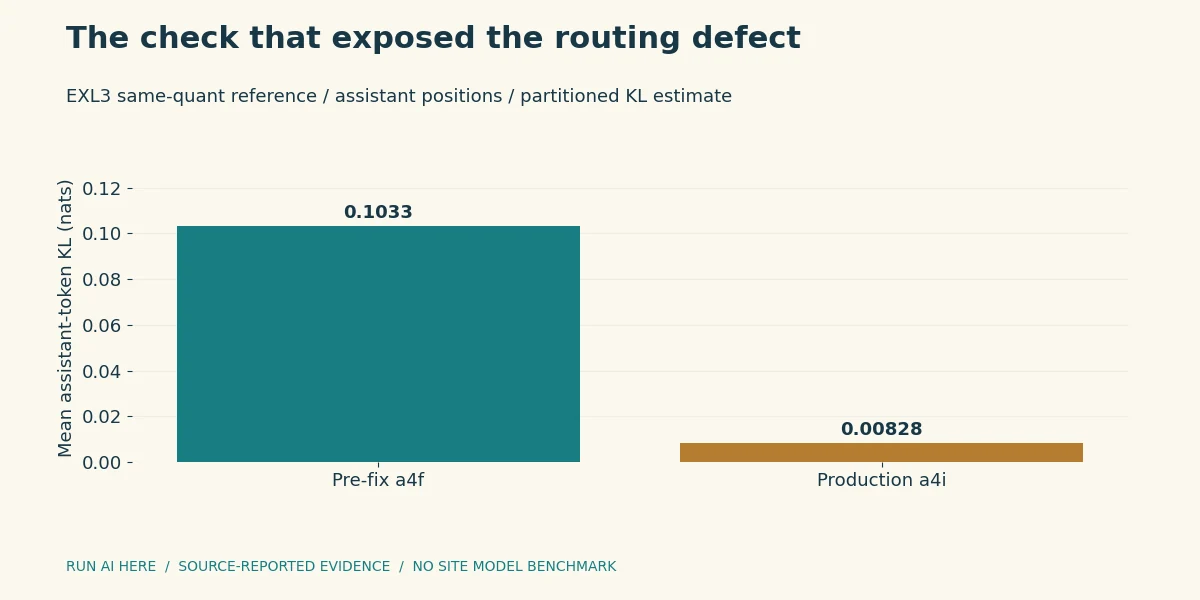
Six texts, 21,066 scored positions; 6,601 assistant positions. Reference is not BF16.
The GSM8K result is instead 188 correct out of 200 selected questions, with eight-shot chain-of-thought prompts and low effort. It is 94.0 percent on that subset, not the full 1,319-question test and not a matched comparison to a zero-shot, thinking-off deployment. Different prompting and answer extraction can change what a score means even before hardware enters the comparison.
Reliability and evaluator limits are part of the score
The raw tool-evaluation report uses tool-eval-bench 2.6.1.dev39+gd3352edf5, 88 hard scenarios and eight trials. The listed trial scores are 88, 88, 86, 87, 88, 88, 88 and 89. The publisher reports a rounded mean 87.8, SD 0.9 and 95 percent interval [87.1, 88.2]; the interval calculation is not independently verified here. The top-level final score is the last trial, not the mean. Pass^8 is 76.1 percent, a stricter repeated-success view than the average score.
The same ledger's IFEval uses a custom evaluator: strict prompt accuracy is 427/541, or 78.9 percent, and instruction-level accuracy is 710/834, or 85.1 percent. A known suspicious title-format failure motivates checking the evaluator against an official implementation. One suspected false negative does not prove that every discrepancy goes in one direction, so this guide does not certify the score as a mathematical lower bound. Its evaluator remains unverified.
The needle report records 20 successful single-fact probes over four lengths and five depths, through 997,952 actual tokens. The initial 120-second timeout is raised to 3,600 seconds for the same-content rerun. That is finite retrieval evidence, not demonstrated long-context reasoning, concurrency at the full window or a whole-workload peak-memory trace.
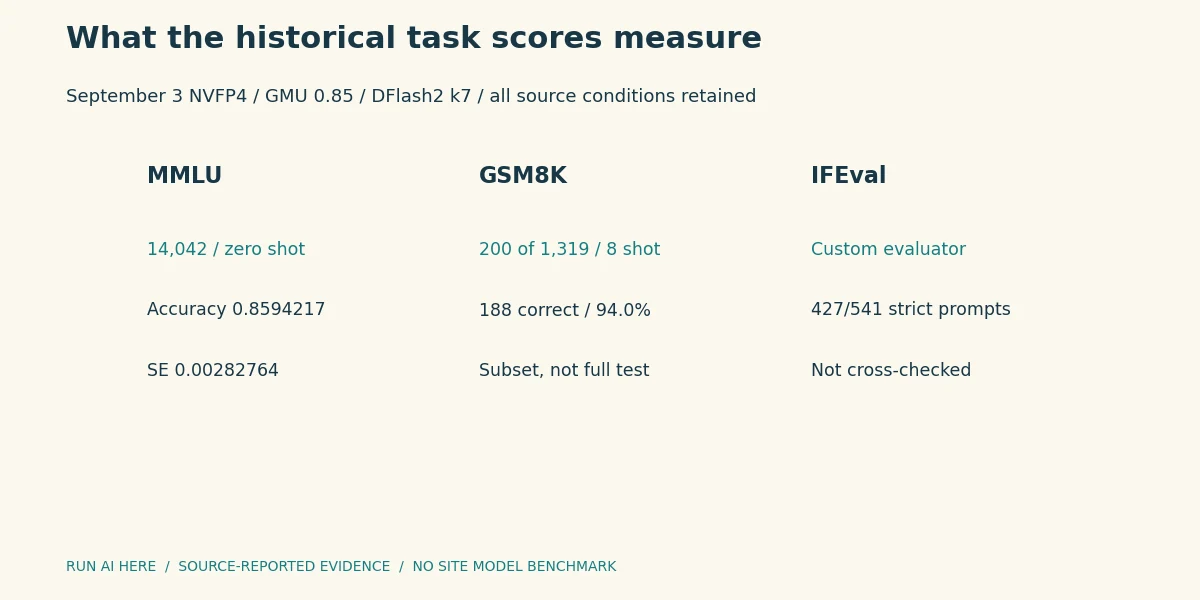
MMLU uses loglikelihood and no sampling. These are heterogeneous task scores, not a composite.
The EXL3 notice changes what can be quoted
The October 8 correctness notice identifies an unloaded e_score_correction_bias in the old cuda-exl3 plugin. The router uses zeros instead of the model's balancing bias and selects wrong experts. The author withdraws the old EXL3 repository's task scores, including its prior MMLU, tool, GSM8K, IFEval and needle panels, until they are rerun. Old speed numbers also do not define corrected routing's speed.
That notice concerns the EXL3 plugin line. It is not evidence that a separate Marlin NVFP4 implementation has the same defect. Conversely, the separate NVFP4 scores cannot validate the corrected EXL3 model. Keeping those two statements together avoids both discarding unrelated measurements without evidence and filling a corrected stack's missing task scores with a sibling stack's results.
The new TP3 main recipe pins target weights to 2a30229e67012798ba9f0cd832bb78abf4c363d5, base vLLM to 21d93d0d8c0e9627900020382bfce4730e61cab7 and production cuda-exl3 to 448f1d6b8964b96e7d4e299494538bfc240149ef. It adds a boot gate for the bias. The reported local image ID is retained as an ID, not mislabelled a registry digest. Published patch comments differ from the files in that image, so a byte-identical rebuild is not promised. TP2 has not been ported or tested on this corrected path.
The rerun is probability health, not a new task leaderboard
The detailed KL investigation compares the same quantized checkpoint to exllamav3 1.5.4, not to BF16. Six author-written texts have 21,072 tokens, 21,066 scored positions and 6,601 assistant positions. The partitioned reference-top-512-plus-remainder estimate is a lower-bound KL measurement; assistant positions form the headline because other regions behave differently.
Pre-fix assistant KL is 0.1033; production a4i is 0.00828. The detailed table's perplexity 2.222 belongs to the bias-fix a4g arm, against reference 2.224. Production a4i perplexity is unreported in that table, so it remains null even where a short summary groups the numbers together. Neither value gives task accuracy. The prepared text set and full per-position logits are not public, which limits independent reproduction.
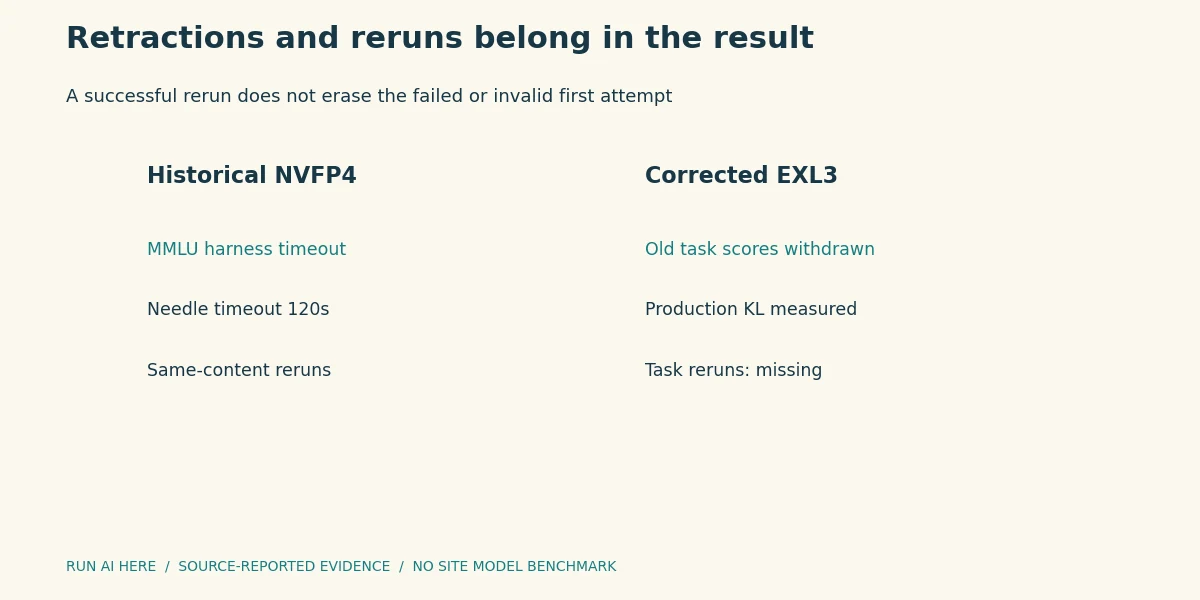
Bias-fix perplexity 2.222 belongs to a4g. Production a4i perplexity remains null in the detailed table.
The current quality-gate document explicitly says task benchmarks have not been rerun on the corrected stack. The useful publication is therefore a correction with a missing-result ledger: historical NVFP4 tasks retain their own date and harness; withdrawn EXL3 tasks stay withdrawn; corrected EXL3 probability checks retain their reference; future task reruns remain pending. A search or AI summary should return those states alongside any numeric excerpt, rather than selecting the most flattering score from an older table.
Continue with the source material
Original sources and evidence boundary
Checked 2026-10-18. Source declarations and community measurements retain their own conditions. No independent model benchmark was run by Run AI Here.
- NNNtrance · docs/06-benchmarks.md Document revision:
eb11cef295c107c5bd21402106eacea5ebd1fbf3Document checksum and matching source record
SHA-256
Read source conditions →e60fb038ca4ab3785a68abe0cdf0906452052e091443c201f90d93ea7590a495 - NNNtrance · tracks/tp3-main/README.md Document revision:
83ed1eccd93a15ae9efe495dbee016cd57823c5fDocument checksum and matching source record
SHA-256
Read source conditions →6cb79207b37211c1542b98dfe26408e7d0b741133be67286db7838c48976223f - NNNtrance · README.md Document revision:
eb11cef295c107c5bd21402106eacea5ebd1fbf3Document checksum and matching source record
SHA-256
Read source conditions →5912e935333340dbd77ecd01cec8c7e207990bc6f446341f741bb3bd66d6cf4b - NNNtrance · docs/05-memory-ladder.md Document revision:
eb11cef295c107c5bd21402106eacea5ebd1fbf3Document checksum and matching source record
SHA-256
Read source conditions →29874450acd65f1e6614bd3fc04fe0815ef8b9036007867b8446e63ebb4092de - NNNtrance · results/mmlu/mmlu-full-lm-eval-results.json Document revision:
eb11cef295c107c5bd21402106eacea5ebd1fbf3Document checksum and matching source record
SHA-256
Read source conditions →86ed1c5586cfe259e7ff438fff2baf1df2dd2ebc069b3db5bbce0763c9ef03c8 - NNNtrance · results/tool-eval-bench/tool-eval-bench-8-trials.json Document revision:
eb11cef295c107c5bd21402106eacea5ebd1fbf3Document checksum and matching source record
SHA-256
Read source conditions →7a46e4d7b52956a0fb0662838081b526e7ceeb30e14e553648227bade4dc6df5 - NNNtrance · results/needle/needle-in-a-haystack-report.md Document revision:
eb11cef295c107c5bd21402106eacea5ebd1fbf3Document checksum and matching source record
SHA-256
Read source conditions →cceef7123bbb9e9d34c2c6a44bc00055b81f896cbf51977053766e770c30ae3d - NNNtrance · results/README.md Document revision:
eb11cef295c107c5bd21402106eacea5ebd1fbf3Document checksum and matching source record
SHA-256
Read source conditions →15388126cd782399e618a52b5cbcd2c5af46f7de347f6903e4705d719f84b037 - NNNtrance · README.md Document revision:
83ed1eccd93a15ae9efe495dbee016cd57823c5fDocument checksum and matching source record
SHA-256
Read source conditions →a399f1dd57e66933e4b947eb4f14212815dc0526deee69942624759b178038d0 - NNNtrance · results/main-stack/kl-health.md Document revision:
83ed1eccd93a15ae9efe495dbee016cd57823c5fDocument checksum and matching source record
SHA-256
Read source conditions →9fcb41cb68098fe0e982f727f6c57b86656748fd41bbd6a0f64dfc794dbb2ba1 - NNNtrance · results/main-stack/quality-gates.md Document revision:
83ed1eccd93a15ae9efe495dbee016cd57823c5fDocument checksum and matching source record
SHA-256
Read source conditions →9d0387be075bd6c214ab8e9b2bb70a46577b5052884c06c0db02d1869b295f28 - NNNtrance · docs/20-main-stack.md Document revision:
83ed1eccd93a15ae9efe495dbee016cd57823c5fDocument checksum and matching source record
SHA-256
Read source conditions →b7ef6f4c82dd1bfa693452cb1fcfb57c8f3270455ca894b667e24048cc20786d - NNNtrance · README.md Document revision:
eb11cef295c107c5bd21402106eacea5ebd1fbf3Document checksum and matching source record
SHA-256
Read source conditions →5912e935333340dbd77ecd01cec8c7e207990bc6f446341f741bb3bd66d6cf4b - NNNtrance · docs/05-memory-ladder.md Document revision:
eb11cef295c107c5bd21402106eacea5ebd1fbf3Document checksum and matching source record
SHA-256
Read source conditions →29874450acd65f1e6614bd3fc04fe0815ef8b9036007867b8446e63ebb4092de - NNNtrance · results/mmlu/mmlu-full-lm-eval-results.json Document revision:
eb11cef295c107c5bd21402106eacea5ebd1fbf3Document checksum and matching source record
SHA-256
Read source conditions →86ed1c5586cfe259e7ff438fff2baf1df2dd2ebc069b3db5bbce0763c9ef03c8 - NNNtrance · results/tool-eval-bench/tool-eval-bench-8-trials.json Document revision:
eb11cef295c107c5bd21402106eacea5ebd1fbf3Document checksum and matching source record
SHA-256
Read source conditions →7a46e4d7b52956a0fb0662838081b526e7ceeb30e14e553648227bade4dc6df5 - NNNtrance · results/needle/needle-in-a-haystack-report.md Document revision:
eb11cef295c107c5bd21402106eacea5ebd1fbf3Document checksum and matching source record
SHA-256
Read source conditions →cceef7123bbb9e9d34c2c6a44bc00055b81f896cbf51977053766e770c30ae3d - NNNtrance · results/README.md Document revision:
eb11cef295c107c5bd21402106eacea5ebd1fbf3Document checksum and matching source record
SHA-256
Read source conditions →15388126cd782399e618a52b5cbcd2c5af46f7de347f6903e4705d719f84b037 - NNNtrance · README.md Document revision:
83ed1eccd93a15ae9efe495dbee016cd57823c5fDocument checksum and matching source record
SHA-256
Read source conditions →a399f1dd57e66933e4b947eb4f14212815dc0526deee69942624759b178038d0 - NNNtrance · results/main-stack/kl-health.md Document revision:
83ed1eccd93a15ae9efe495dbee016cd57823c5fDocument checksum and matching source record
SHA-256
Read source conditions →9fcb41cb68098fe0e982f727f6c57b86656748fd41bbd6a0f64dfc794dbb2ba1 - NNNtrance · results/main-stack/quality-gates.md Document revision:
83ed1eccd93a15ae9efe495dbee016cd57823c5fDocument checksum and matching source record
SHA-256
Read source conditions →9d0387be075bd6c214ab8e9b2bb70a46577b5052884c06c0db02d1869b295f28 - NNNtrance · docs/20-main-stack.md Document revision:
83ed1eccd93a15ae9efe495dbee016cd57823c5fDocument checksum and matching source record
SHA-256
Read source conditions →b7ef6f4c82dd1bfa693452cb1fcfb57c8f3270455ca894b667e24048cc20786d
AI-assisted draft, reviewed and edited by Run AI Here. No NVFP4 score is assigned to the corrected EXL3 deployment. No cross-stack ranking. Original authors retain attribution. Corrections should identify the source revision and affected statement.