
THE PRACTICAL ANSWER
The recipe is a concrete deployment candidate, but speed and quality use different request shapes and thinking modes. The source custom quality bar passes while its non-inferiority flags are false; preserve both and leave the executed local image digest unknown.
The Chisel community recipe is a concrete Qwen3.8-27B deployment candidate for one DGX Spark. Its value is the pinned serving recipe and separate speed and quality records. Read the workload and quality gate before repeating a headline rate: the published results use different prompt shapes, cache settings and thinking modes.
This note reads yuanlin2004’s replay recipe, checked on 18 October 2026. The underlying local cohort is filed under October 15; some sessions cross UTC midnight. Run AI Here has not installed the recipe or run the model.
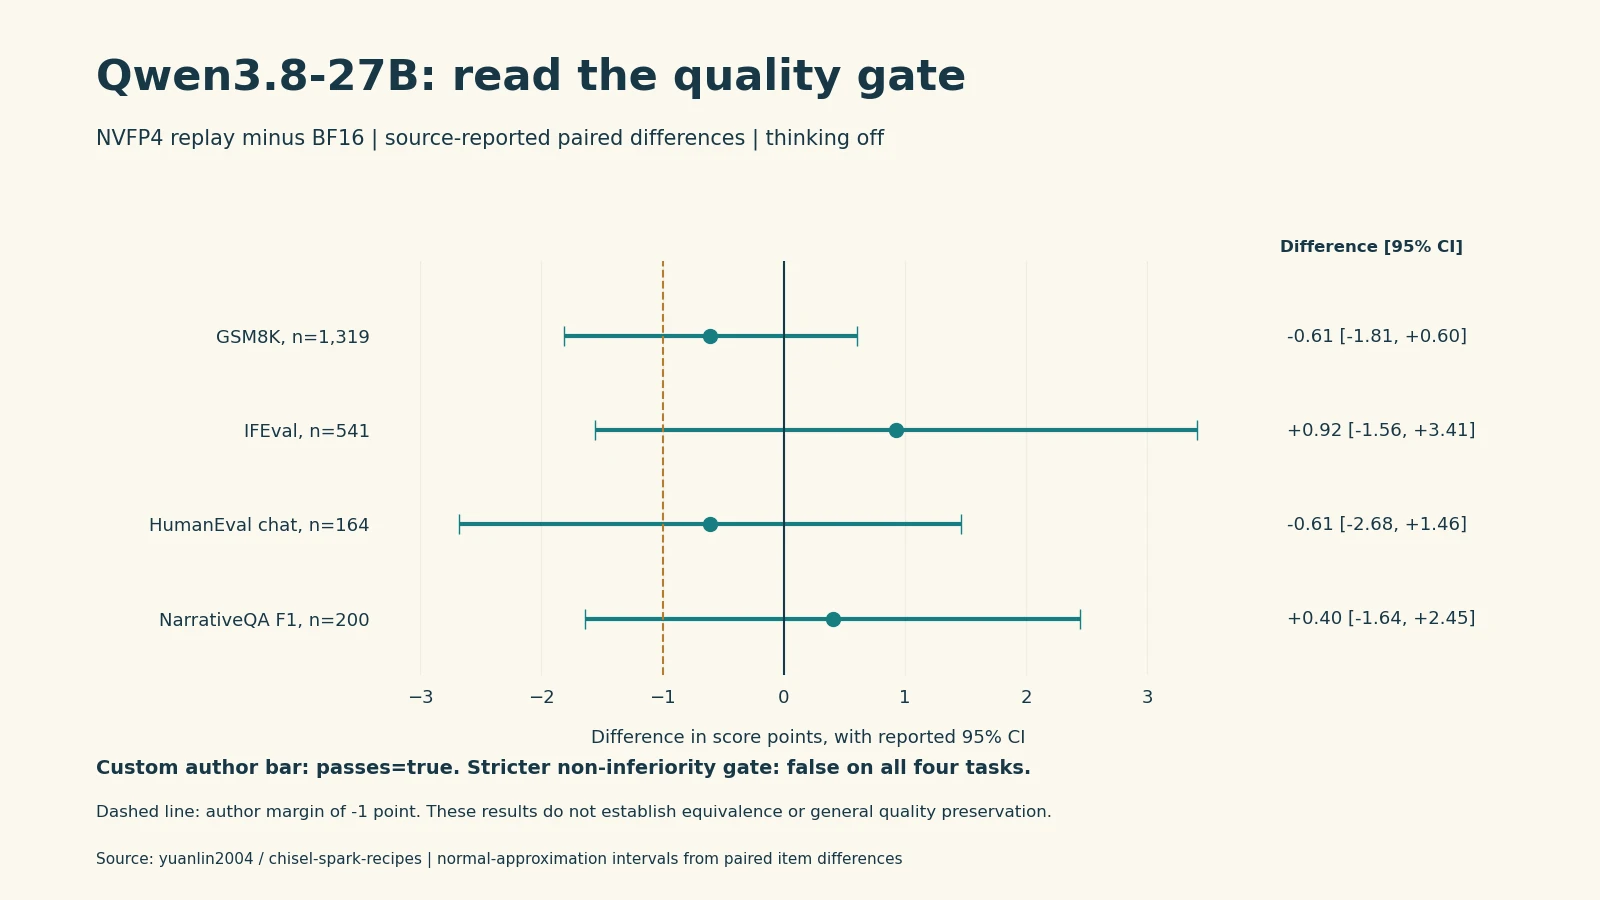
Figure: calculated positions use the source comparison JSON directly. Intervals describe paired task-score differences, not speed variation. Passing the author’s custom bar does not establish non-inferiority.
Identify the target, drafter and actual image separately
The target is unsloth/Qwen3.8-27B-NVFP4, reported with revision prefix f0b7c9e7. The full executed weight revision is not provided. The drafter is yuanlin2004/Qwen3.8-27B-Chisel-DFlash2-NVFP4-drafter, with its weight-file SHA-256 retained in the export. Ten draft tokens, bf16 GDN state and chisel-passes 0.1.0 are part of the configuration. GDN state dtype does not fill an unreported attention-KV dtype.
The environment names vLLM 0.31.1rc1.dev380, driver 580.178.04 and a 2,000 MHz GPU cap. It explicitly says the main tests used a local build with the plugin preinstalled, while the published recipe installs it at startup. The base image has a digest; the saved server.image contains an empty array. Keep the executed local image digest unknown. Environment.
The YAML configures TP1, memory utilization 0.60, a 262,144-token cap and up to four sequences. Those settings do not prove four simultaneous near-limit requests fit. The plugins change recurrent-state handling and the draft output head; the target verification path retains its full vocabulary according to the author. Source code for these recipe plugins is public, while the broader Chisel project is described as not yet public. Pinned serving recipe.
Four numbers belong to two speed cohorts
| Local test | Reported observation | Keep with the value |
|---|---|---|
| Mixed prompts | 15.35 ms/token median decode latency | One user; thinking on, medium; at most 256 output tokens |
| Same mixed prompts | 241 ms median TTFT | First-token waiting, separate from decode |
| llama-benchy at 16K context | 30.0 tokens/s, one user | 2,048-token prompt stage, 128 output tokens, prefix cache on |
| Same llama-benchy shape | 58.0 tokens/s total, two users | Aggregate across both users, not a per-user rate |
The mixed test has 25 prompts: nine chat, nine code, six JSON-schema and one long story. Two fresh-start sessions each repeat that set three times. Decode latency excludes the first-token wait. The llama-benchy cohort uses version 0.4.0 and five runs per session. Its thinking override is not explicitly supplied in the method summary and remains unknown in the extraction. These are local runs of an arena-shaped benchmark, separate from the hosted arena entry. Method.
A median latency is not whole-request throughput. Nor can a two-user total be compared directly with the one-user latency. Use the timing guide when deciding which measure fits an application. Avoid a “fastest” verdict across these conditions.
Read the quality result beyond the pass flag
The source compares against Qwen/Qwen3.8-27B BF16 at 1d4bf0f2ff6012fd82039f2fa52739d0dd7c60c0, with bf16 KV. Quality evaluation uses lm-evaluation-harness 0.4.13, chat templates, greedy decoding and thinking off. The BF16 cohort is filed under October 9; the comparison JSON retains older original candidate paths. Candidate image, clock and plugin settings must not be silently assigned to the reference arm.
| Task and sample count | BF16 score | NVFP4 replay score | Difference, points [reported 95% CI] |
|---|---|---|---|
| GSM8K 5-shot, 1,319 | 90.07 | 89.46 | −0.61 [−1.81, +0.60] |
| IFEval strict, 541 | 80.96 | 81.89 | +0.92 [−1.56, +3.41] |
| HumanEval chat pass@1, 164 | 95.12 | 94.51 | −0.61 [−2.68, +1.46] |
| NarrativeQA F1, 200 | 34.83 | 35.24 | +0.40 [−1.64, +2.45] |
The custom bar requires at least 97% recovery, a permitted answer-length ratio and no task flagged clearly worse. It passes. A stricter flag requires the lower interval bound to exceed a loss of one point; all four non_inferior flags are false. Both results must survive an AI summary. Exact comparison JSON.
The comparison code computes paired item differences and a normal-approximation interval, mean ± 1.96 standard errors. These are not bootstrap intervals. Intervals crossing zero do not prove equivalence, and scores on four tasks do not guarantee general quality preservation.
A useful local acceptance plan
Before adopting the recipe, identify the quantized artifact, drafter, plugins and executed image. Check the required API features and memory allocation at your actual context and concurrency. Then evaluate both timing and correctness on representative prompts. Keep speed thinking-on results separate from thinking-off quality tests. The source record and adjacent JSON/Markdown retain the twelve selected observations, four paired comparisons and missing identifiers.
Continue with the source material
Original sources and evidence boundary
Checked 2026-10-18. Source declarations and community measurements retain their own conditions. No independent model benchmark was run by Run AI Here.
- yuanlin2004 · recipes/qwen3.8-27b/chisel-nvfp4-dflash2-replay.md Document revision:
84feafddff1e834bd16b849c827eed11676e5934Document checksum and matching source record
SHA-256
Read source conditions →5da566bc197bf4ba29c7c4d343b3c0362577de023425369a1a6ea9e53de95321 - yuanlin2004 · recipes/qwen3.8-27b/chisel-nvfp4-dflash2-replay.yaml Document revision:
84feafddff1e834bd16b849c827eed11676e5934Document checksum and matching source record
SHA-256
Read source conditions →028f2badf76407546be67b8bd93e2e81aae8ad5d00076e20b8bd8835021a1ede - yuanlin2004 · results/qwen3.8-27b/chisel-nvfp4-dflash2-replay/2026-10-15/ENVIRONMENT.md Document revision:
84feafddff1e834bd16b849c827eed11676e5934Document checksum and matching source record
SHA-256
Read source conditions →349c8de9b51a1df3ebba677db79d4e62c9a652a6dc225965f7515b80583d471a - yuanlin2004 · results/qwen3.8-27b/chisel-nvfp4-dflash2-replay/2026-10-15/METHOD.md Document revision:
84feafddff1e834bd16b849c827eed11676e5934Document checksum and matching source record
SHA-256
Read source conditions →072fb07c8e46bb6e1e7a4c8a9416b94a87863cfc60dfde60f127e9243363dd8e - yuanlin2004 · results/qwen3.8-27b/chisel-nvfp4-dflash2-replay/2026-10-15/server.image Document revision:
84feafddff1e834bd16b849c827eed11676e5934Document checksum and matching source record
SHA-256
Read source conditions →37517e5f3dc66819f61f5a7bb8ace1921282415f10551d2defa5c3eb0985b570 - yuanlin2004 · results/qwen3.8-27b/chisel-nvfp4-dflash2-replay/2026-10-15/quality/compare-vs-bf16.json Document revision:
84feafddff1e834bd16b849c827eed11676e5934Document checksum and matching source record
SHA-256
Read source conditions →46aec52dd7d9d842b58c710904f6af19960f1196a7f05f2c834f4532481121fb - yuanlin2004 · tools/compare_quality.py Document revision:
84feafddff1e834bd16b849c827eed11676e5934Document checksum and matching source record
SHA-256
Read source conditions →ee52180fce64fa6948d7516ac42f7f5fd0ef143584d2c284d6aa19f6fdecb783 - Qwen · README.md Document revision:
1d4bf0f2ff6012fd82039f2fa52739d0dd7c60c0Document checksum and matching source record
SHA-256
Read source conditions →57e4bdb258ee1a7d2635c5174ebd4e56abe392505cdb5f8bbb356b0dc4293641
AI-assisted draft, reviewed and edited by Run AI Here. Original paired differences and reported normal-approximation 95% intervals. The source custom bar passes, while every non-inferiority flag is false. These task results do not establish equivalence or general quality preservation. Original authors retain attribution. Corrections should identify the source revision and affected statement.